A customer asks ChatGPT about your company and the model names three competitors, or describes the business using facts two years out of date. The site ranks, search traffic comes in, conversions hold. The usual first move is to rewrite the copy, add expertise, build an FAQ. It is a logical guess, that there is too little content, and it rarely holds up. The model answers from what reached it, not from what you published.
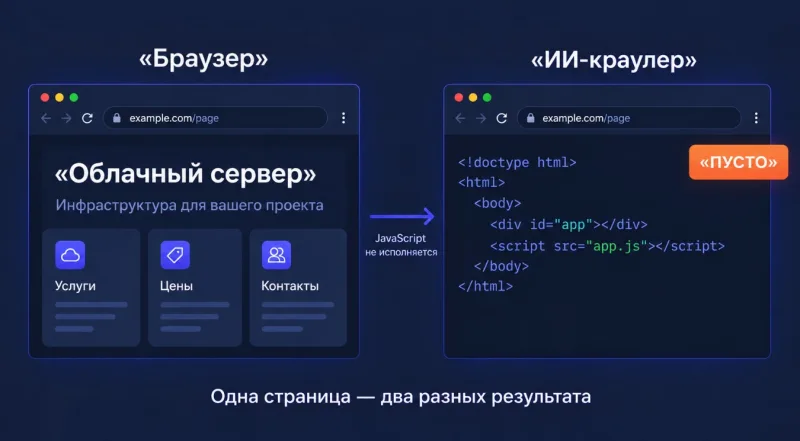
Running our own site through queries to several models and checking what their infrastructure actually receives produced a plainer explanation. Some AI crawlers do not execute JavaScript. For a site assembled in the browser that means the model gets an empty shell instead of the article: the reader sees a finished page, the crawler gets a file with no text in it.
Where the content is lost
Client-side rendering is the first place. If copy loads through JavaScript, a crawler without JS support sees only the markup. Opening the page with JS disabled, or reading what the server returns in the raw HTML, shows whether the text is there at all. Files such as robots.txt can block crawling, sometimes for the whole site, sometimes for the sections that carry the content. Dynamic elements are the third gap: FAQs, accordions and tabs that open on click usually load by script, so the answer a user sees never reaches the model.
Diagnosis comes before editing. Check the page source for the main text, check what the server returns without JavaScript, check the robots.txt rules that apply to AI crawlers, then compare what different models say about the company. If the problem is rendering, server-side rendering delivers finished HTML with the text in it. A simplified static version of key pages works where a full move to SSR is hard. Important material, meaning FAQs, service descriptions and key facts, is better held in the markup than in scripts. Access is worth confirming as well, so that AI crawlers are not shut out where the content should be open.
Rewriting does not fix any of this. However good the article becomes, nothing changes if an empty shell is what arrives. Check that the content gets through first. Quality is the second question.


