The demo works, then it does not
A first RAG prototype usually takes an evening: load the documents, build embeddings, wire up vector search. It appears to understand the questions. Trouble starts later. Search slows at real volumes. After metadata filtering, results vanish. The team spends weeks on a system the project did not need.
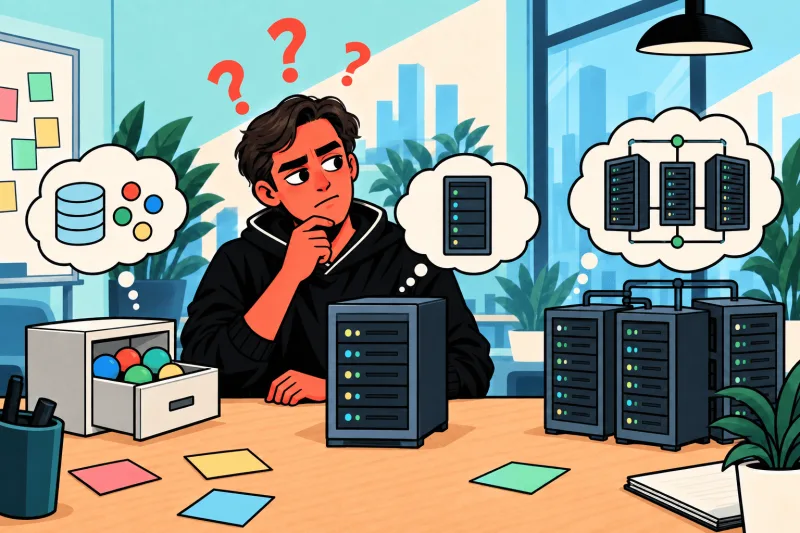
Picking a vector search database is not a race for the most advanced option. It is an answer to how much load you actually carry. Three options: PostgreSQL with pgvector, Qdrant, Milvus.
When PostgreSQL with pgvector is enough
pgvector is a PostgreSQL extension that adds a type for storing vectors and search over them. If the data already sits in Postgres, you get vector search without a new service. One backup, one monitoring stack, familiar SQL.
It is sufficient when vector volume is small or medium, metadata filters are simple and fit ordinary indexes, the team already knows Postgres, and latency is not critical. The gain is fewer moving parts: no syncing data across two stores, no separate access layer. For many internal RAG systems that is more than enough.
There is a limit. As vectors grow and filters get complex, Postgres starts to strain. Filtered search across several fields can return nothing or slow down sharply. That is a signal to check the architecture, not to swap the database at once.
Qdrant: when search should move out
Qdrant is a separate vector database. Its point is to carry the vector search with filtering, without the load of a relational DBMS behind it.
Moving search to Qdrant makes sense when volume grows and Postgres stops holding latency, when metadata filtering has become the main pain, or when search behaviour under load needs to be more predictable. The price is new infrastructure: a second service to deploy, update and monitor, and data to sync between the main store and Qdrant. That is real work and belongs in the plan. With simple filters and modest volumes, Qdrant adds complexity without much return.
Milvus: when the complexity is justified
Milvus is a heavy distributed vector search system. It is built for large volumes and serious load, and it demands matching infrastructure.
Its complexity pays off when vectors are genuinely numerous, load is high and distributed, and scaling cannot be covered by a single machine. For a typical project with documents and an internal chat, Milvus is almost always excessive. Deploying it is not hard; maintaining it is a separate job, and the team ends up running a system bigger than the product needs.
How to choose without extra architecture
Start by checking whether pgvector suffices. If the data is already in Postgres, begin there and measure latency on real queries with real filters. Not on demo data.
If you hit the limit, move to Qdrant. Pulling search into a separate database solves filtering and load problems but adds a service and synchronisation. It is a reasonable step once the pain is measured.
Choose Milvus only when scale genuinely calls for a distributed system. The main mistake is building for expected load rather than current load. Start simple, measure where it hurts, and add complexity as facts warrant.


