longhand — плагин для Claude Code: память по всем сессиям
Индексирует каждую сессию Claude в локальную базу и даёт искать по ней обычными вопросами. Без обращений к API.
/plugin marketplace add anthropics/claude-plugins-community
/plugin install longhand@claude-communityЧто делает longhand
Longhand складывает историю сессий Claude в SQLite и ChromaDB: каждый вызов инструмента, правку файла и блок размышлений. Поиск идёт по смыслу, а не по точному совпадению строк. Всё лежит на вашей машине, наружу ничего не уходит.
Ставится через pip install longhand, дальше longhand setup разбирает накопленную историю, прописывает хуки и настраивает MCP-сервер. Хотите сначала посмотреть — longhand demo поднимает песочницу на поддельном корпусе из трёх сессий и не трогает ~/.claude и ~/.longhand. Инструментов у MCP-сервера много: поиск по смыслу, история файла, статус проекта, воспроизведение правок.
Claude Code сам чистит файлы сессий через несколько недель, и Longhand успевает забрать их в базу до этого. Что не попало в индекс, вернуть уже нечем — поэтому ставить лучше сразу, а не когда понадобилось вспомнить прошлый месяц. Живой разбор текущей сессии пишет только события, без эмбеддингов, так что семантический поиск по ней заработает после завершения сессии или прогона reconcile --fix.
Какие задачи решает
- найти, как вы чинили вебхук Stripe месяц назад
- восстановить цепочку правок в конкретном файле
- поднять историю решений по проекту перед новой задачей
- вернуть удалённые Claude файлы сессий
- понять, что происходило в длинной сессии, не читая её целиком
Примеры запросов агенту
- Найди в истории, как мы обходили ошибку с вебхуком Stripe
- Покажи, что менялось в
src/auth.tsза последние сессии - Дай статус проекта за последние 7 дней
Как установить longhand
Через маркетплейс плагинов
/plugin marketplace add anthropics/claude-plugins-community/plugin install longhand@claude-communityПо шагам, с командами для каждой платформы: Плагины Claude Code: маркетплейсы, установка и как собрать свой
Вопросы о longhand
Как установить longhand в Claude Code?
Добавьте маркетплейс: /plugin marketplace add anthropics/claude-plugins-community, затем поставьте плагин: /plugin install longhand@claude-community.
Что делает longhand?
Индексирует сессии Claude в локальную SQLite и ChromaDB и открывает по ним поиск на естественном языке. Плюс даёт историю файлов, статус проекта и воспроизведение правок.
Нужны ли ключи API для работы longhand?
Нет, запросы не уходят в сеть, всё считается на вашей машине. Нужен Python 3.10 или новее.
Исходный текст
SKILL.md · MIT
<!-- mcp-name: io.github.Wynelson94/longhand -->
# Longhand
**Using Codex too?** [Share one memory archive between Claude Code and Codex](https://github.com/Wynelson94/longhand/blob/main/docs/codex.md).
[](https://glama.ai/mcp/servers/Wynelson94/longhand)
[](https://pypi.org/project/longhand/)



[](https://safeskill.dev/scan/wynelson94-longhand)
**Persistent local memory for Claude Code.** Every tool call, every file edit, every thinking block from every Claude Code session — stored verbatim on your machine. Searchable, replayable, and recallable by fuzzy natural-language questions. Zero API calls. Zero summaries. Zero decisions made by an AI about what's worth remembering.
> **Claude Code quietly rotates your session files after a few weeks.** Longhand captures them into SQLite before they're gone. Once ingested, your history stays forever — even after the source JSONL files are deleted. Install early; the past you don't capture is unrecoverable.
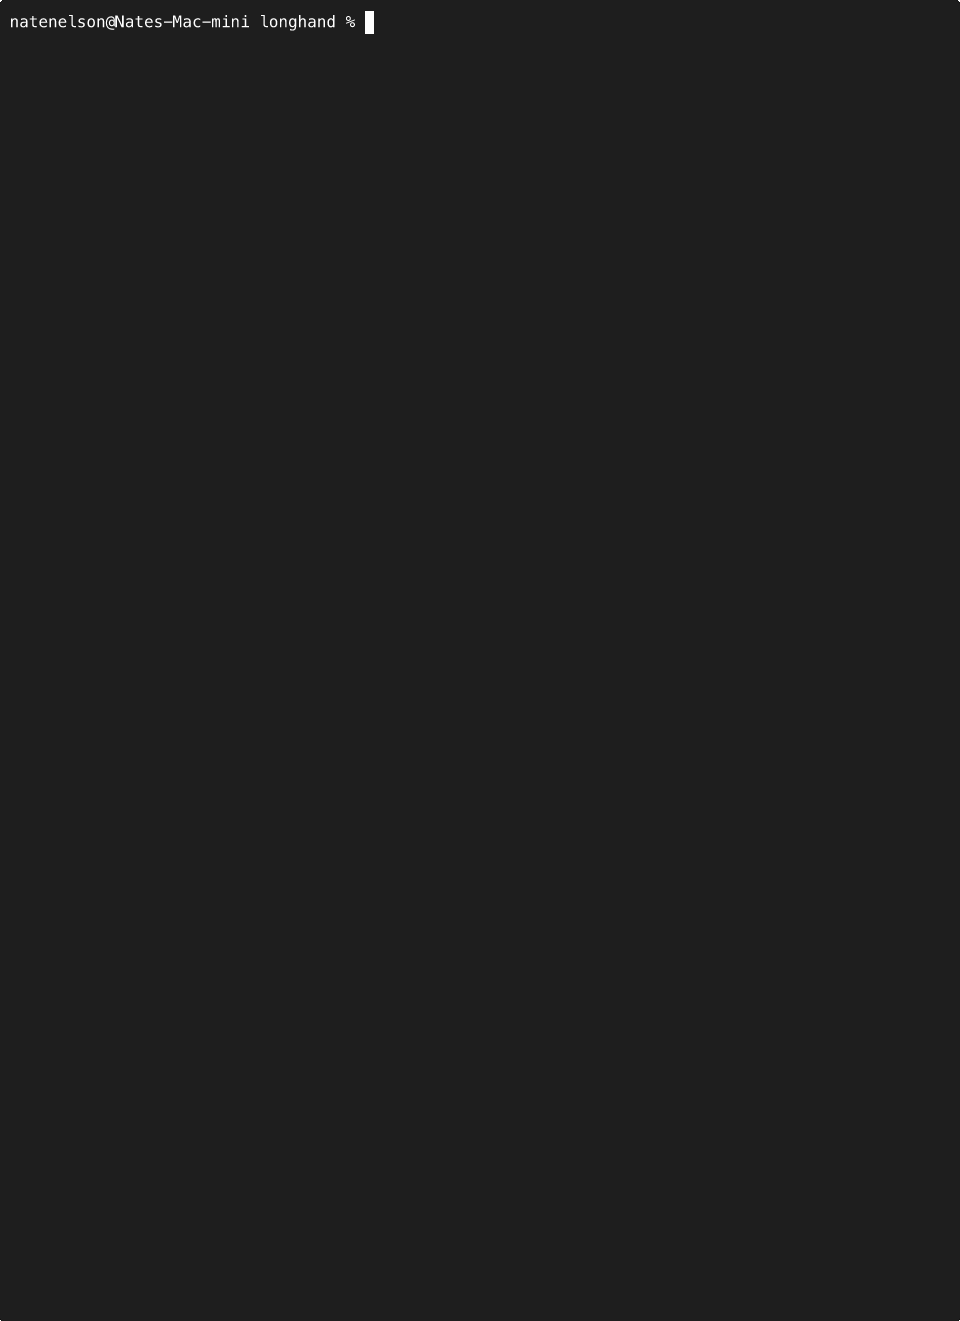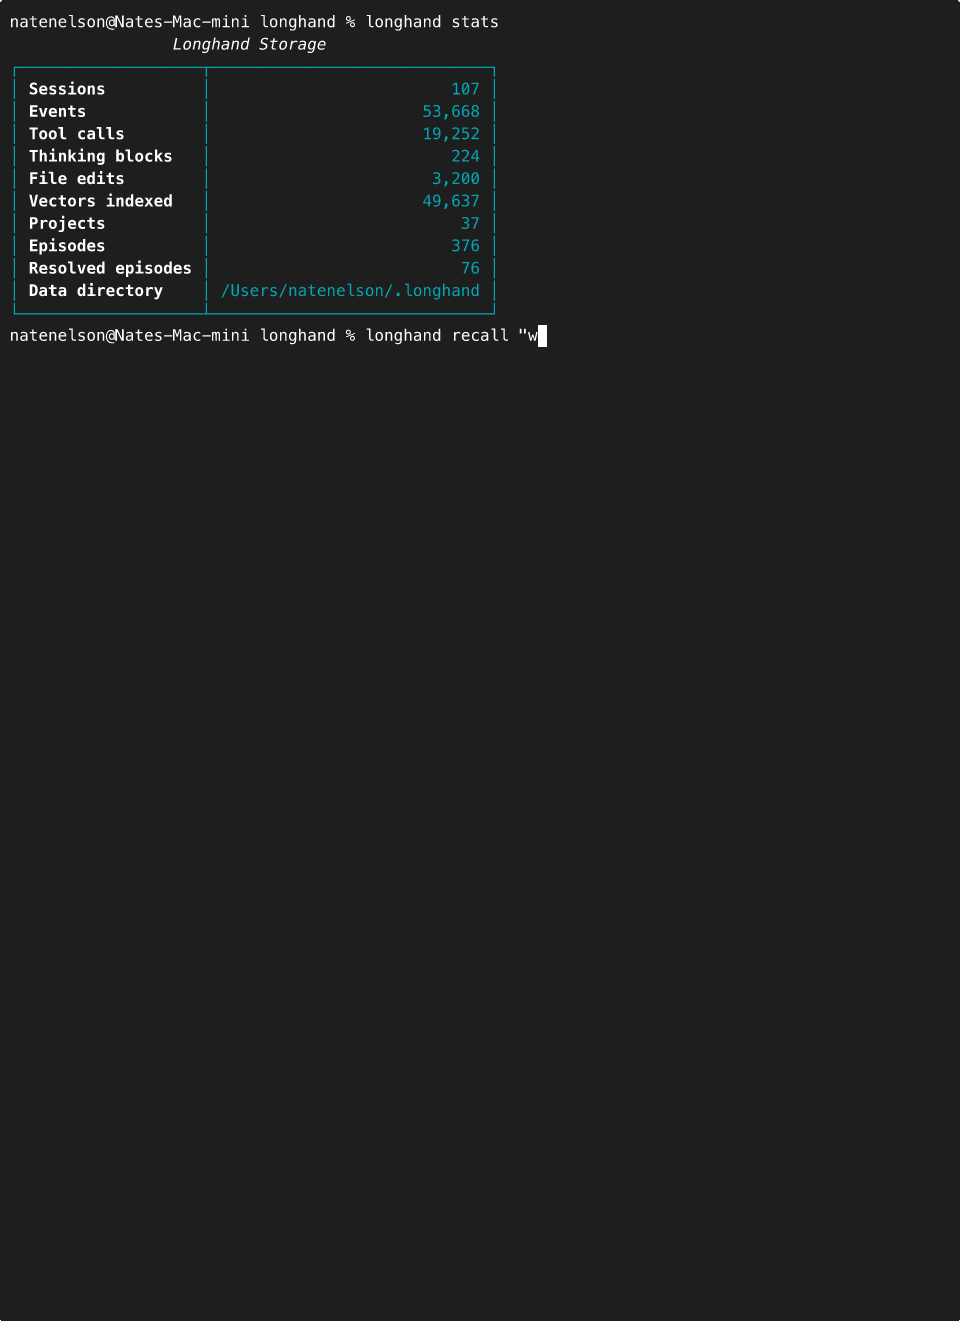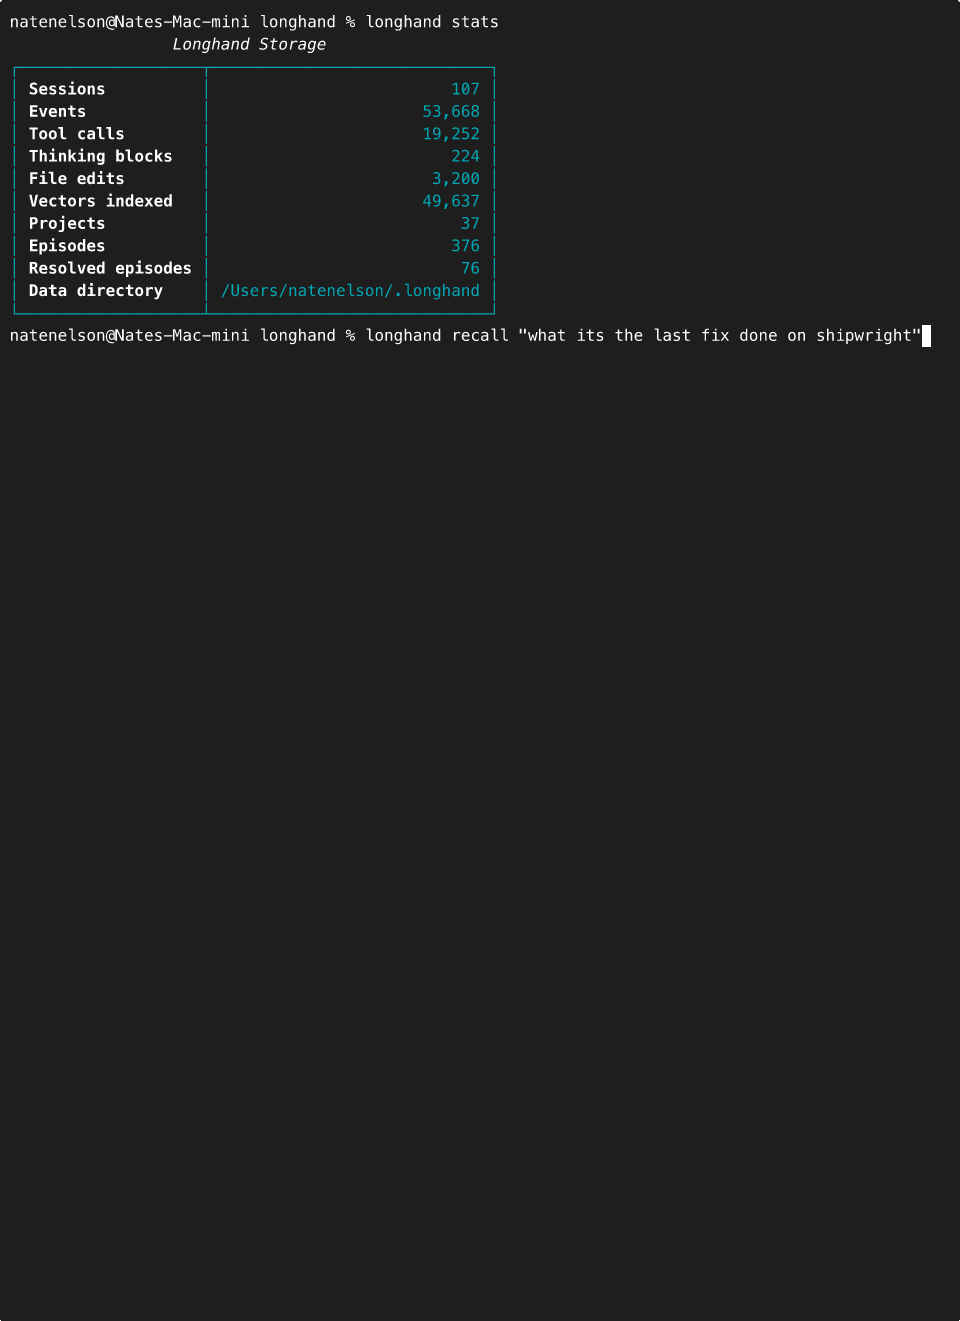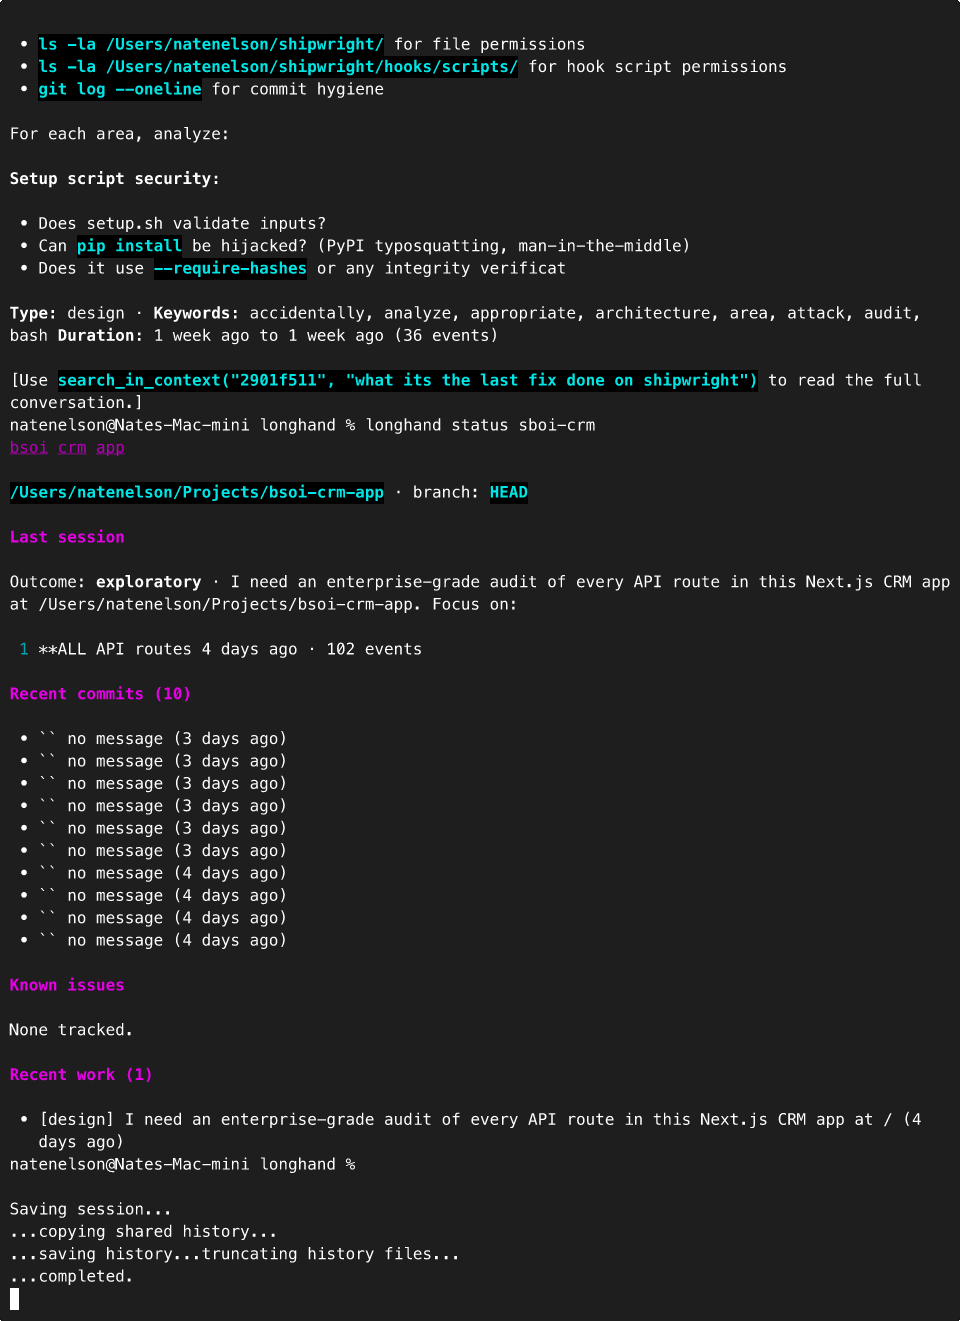
> **If you have 20+ Claude Code sessions in `~/.claude/projects/`, Longhand can search across every fix, decision, and conversation you've had in ~29ms — without a single API call.**
> **Does it use a lot of tokens? No — the tools you'll use most are capped by design.** A full `recall` across 100+ sessions returns ~4K tokens. Reading one raw session JSONL costs 10–50× more. See [Token budget](#token-budget) for which tools cap output and which don't.
```bash
pip install longhand
longhand setup # ingest history + install hooks + configure MCP
longhand recall "that stripe webhook bug from last week"
```
**Want to kick the tires first?** Run `longhand demo` for a 60-second walkthrough on a fake 3-session sample corpus — your real `~/.claude` and `~/.longhand` are not touched. The demo seeds a sandboxed store with a Stripe-webhook bug + Supabase auth migration + downstream 401 fix, then runs cross-session recall and project-status so you can see what the output looks like before committing.
```bash
pip install longhand
longhand demo # sandboxed; cleans up afterwards (pass --keep to explore)
```
**Upgrading to 1.0.0?** This is the release that closes the deprecation window 0.13 opened. Everything removed here has been warning since 0.13.0:
- Four CLI aliases are gone: `patterns` → `recall "<topic>"`, `recap` → `status --days N`, `continue` → `status --session <prefix>`, `reanalyze` → `analyze --all`.
- **The `reconcile` MCP tool now defaults to a dry run.** If you have an agent loop that relied on the implicit heal, pass `fix=true` explicitly. Dry runs tell you so in the payload.
- Six retired MCP tools left the listing (19 → 13) but **still answer forever** with a migration note — retired names live in users' own `CLAUDE.md` files and must never hard-fail.
- New: [COMPATIBILITY.md](https://github.com/Wynelson94/longhand/blob/main/COMPATIBILITY.md) states what 1.x guarantees and what it doesn't.
Your database needs nothing. Migrations are automatic and a 0.11+ store opens on any later 1.x — that's Promise 2, and there's a real 0.11-schema fixture in the test suite proving it.
**Upgrading to 1.2.x?** No removals, just fixes worth knowing about:
- **1.2.3:** MCP `get_session_timeline`'s `tail` now returns the true last N events on sessions over 5,000 events — it used to return the middle. `setup`'s closing hint stopped suggesting `recap` (removed at 1.0) and now suggests `status --days 7`. Recall's footers and `get_session_timeline`'s own tool description stopped naming `search_in_context` (retired from the tool listing at 1.0, though it still answers) and now point at `search` — the footers spell out the call, `search(session_id=…, query=…, context_events=5)`.
- **1.2.2:** `recall` says so when its top match is much older than the alternatives instead of letting a stale fix read as current (see [Recall Example](#recall-example)). A Codex context-compaction record (`compacted`) no longer trips `doctor`'s transcript-format-drift warning.
- **1.2.1:** MCP `get_session_timeline` had a sentinel bug that made every call return exactly one event, ignoring `limit`/`offset`, unless `tail` was passed explicitly — fixed. `search`'s project auto-scoping no longer overrides an explicit `session_id`.
**Upgrading to 0.13.0?** Nothing breaks — that release opened the v1.0 deprecation window, so every old name kept working while pointing at its replacement:
- `status` is now the single resume command: bare `status` = recent digest (was `recap`), `status <project>` unchanged, `status --session <prefix>` = session tail (was `continue`). The old commands still run and print a pointer; they're removed at v1.0.
- Six MCP tools folded into six survivors with identical parameters (`search_in_context` → `search` + `context_events`, `get_episode` → `find_episodes` + `episode_id`, etc. — full table in the CHANGELOG). The retired names still answer, prefixed with a migration note.
- Hooks can no longer exit nonzero — failures become breadcrumbs in `~/.longhand/logs/` and two new `doctor` rows (`Hook errors`, `Transcript format`) keep them visible.
- "Today"/"yesterday" recall windows now follow your local calendar day instead of UTC's; rankings may shift once if you're not in UTC.
- Windows users: this release fixes a serious bug where the ingest-lock liveness check could terminate other longhand processes.
- New: `LONGHAND_DATA_DIR` relocates the store for the CLI, hooks, and MCP server in one move — except `longhand config --set`, which always writes `~/.longhand/config.json` regardless of the relocated store ([#96](https://github.com/Wynelson94/longhand/issues/96); `--edit` is currently a no-op, same issue). `status --json` / `doctor --json` for scripting.
**Upgrading to 0.9.0?** Live ingestion captures sessions in flight, plan history is preserved as first-class data, and an optional reconciler job keeps the index honest in the background:
- New `longhand ingest-live` command runs from Claude Code's `Stop` hook to tail the active transcript between assistant turns. The in-progress session becomes queryable immediately via `list_sessions`, `get_session_timeline`/`timeline`, `get_file_history`, and `replay_file` — it writes events only, no embeddings, so `recall` and semantic `search` still need the SessionEnd pass (or a `reconcile --fix` pass, which re-ingests with analysis) to see it.
- New `longhand plans list` command and `list_plans` MCP tool surface every Write/Edit to `~/.claude/plans/*.md` across your entire history. Plans are now extracted as their own entity alongside episodes.
- New `longhand schedule install-reconciler` installs an optional launchd job that runs `reconcile --fix` periodically — catches anything the live and post-session hooks missed without you ever thinking about it.
- The Stop hook coexists with the existing SessionEnd hook: live tails the transcript as it grows; SessionEnd does the full analysis pass when the session closes.
**Upgrading to 0.8.1?** Staleness signals now propagate everywhere they belong, and `reconcile` is an MCP tool — Claude can self-heal the index from inside a session:
- `search` and `list_sessions` now wrap the response with `stale: true` + `stale_reason` when the project they're scoped to has on-disk transcripts not yet ingested. Pre-v0.8.1 these returned clean-looking empty results (same silent-failure shape `recall_project_status` was built to catch — just one layer up).
- New `reconcile` MCP tool wraps `longhand reconcile --fix`. After a staleness banner fires, Claude calls `reconcile` directly instead of asking the user to run a CLI command.
- `list_sessions` default `limit` raised from 20 to 50 — active days routinely cross 5+ projects across 5+ sessions; the old default truncated reviews silently.
**Upgrading from 0.7.x or earlier?** Cleaner recall narratives, plus a real bug-finding test layer underneath (from 0.8.0):
- Pre-v0.8 `_compose_fix_summary` prepended a literal `"Intent:"` label to half of all extracted episodes (49% of the reference corpus). The label leaked into every recall narrative for those episodes. **Migration v4 strips it from existing rows on first store open** — no command needed.
- Diff content in `fix_summary` now truncates at whitespace boundaries with a visible `…`, instead of landing mid-token (`phoneNum'`, `family?:'`, `strin'`). Forward-only.
- Narrative footer "Other matches" lines now include the session id so you can drill in.
- New canary harness (`tests/fixtures/corpus/`) anchors regression tests to real shipped bugs. New recall validator (`scripts/recall_diff.py`) snapshots and diffs ranking results against your live corpus — catches regressions pytest can't see.
```bash
pip install --upgrade longhand
longhand recall "..." # migration runs transparently on first open
```
If you're also coming from 0.5.x, run `longhand reconcile --fix` once to re-attribute multi-project sessions per the v0.6 inference improvements (`cd`-into-project sessions now attribute to the project where most work happened, not the first-event cwd). If you're on 0.5.8 or earlier, chain them: `longhand reconcile --fix && longhand analyze --all`. Both are idempotent.
**Large history? (>1 GB of `~/.claude/projects`)** Expect the first-time backfill to take 10–30 minutes on an M-class Mac — most of that wall time is the embedding model running on all your cores (which is why you'll see triple-digit CPU%; that's ONNX doing its job, not a hang). `--skip-analysis` defers the *other* pass — episode/segment extraction and project/session-level vectors — not event embedding, which always runs, so it trims some time but not the dominant cost:
```bash
longhand setup --skip-analysis # events stored + embedded; episodes/segments deferred
longhand analyze --all # fill in episodes + segments + project/session vectors whenever, safe to background
```
`search`, timelines, file history, and commit lookup all work immediately after `--skip-analysis` — every event is embedded regardless of this flag. `recall`'s episode/segment narrative and `recall_project_status` need the `analyze --all` pass to have data to draw on. Typical throughput on an M-class Mac is ~1–2 sessions/sec for full analysis.
> *Status: v1.2.3 — stable, daily-driver tested, security-audited (zero critical findings), on PyPI, available as a Claude Code plugin. Validated against 792 real sessions (786 Claude Code, 6 Codex) across 45 inferred projects (measured 2026-09-27). 617 unit tests passing.*
**Full docs:** [Longhand Wiki](https://github.com/Wynelson94/longhand/wiki) — getting started, CLI reference, MCP tools reference, architecture, and troubleshooting.
---
## The Inversion
Everyone is solving AI memory by making the context window bigger. 1M tokens. 2M tokens. Context-infinite. The whole industry is racing in the same direction: make the model carry more state.
Longhand goes the other direction. **The model doesn't need to carry the memory. The disk does.**
| | Bigger context windows | Longhand |
|----------------------|----------------------------------------------|-----------------------------------|
| **Where it lives** | Rented from a model provider | A SQLite file + ChromaDB on your laptop |
| **Cost per query** | Tokens × dollars | Zero |
| **Privacy** | Goes through someone else's servers | Never leaves your machine |
| **Speed** | Seconds to minutes for large contexts | ~29ms search · ~128ms full recall (warm; see [Stats](#stats)) |
| **Loss** | Attention degrades in the middle of long contexts | Nothing summarized — messages, edits, and thinking blocks stored verbatim† |
| **Persistence** | Dies when the window closes | Lives until you delete the file |
| **Across model versions** | Doesn't transfer | Same data, any model |
| **Offline** | No | Yes |
| **Scales with** | Provider's pricing | Your hard drive |
† Nine Claude Code entry types ([`KNOWN_SKIP_ENTRY_TYPES`](https://github.com/Wynelson94/longhand/blob/main/longhand/parser.py)) and, on the Codex side, three top-level record types ([`CODEX_SKIP_RECORD_TYPES`](https://github.com/Wynelson94/longhand/blob/main/longhand/codex.py)) plus ten `event_msg` kinds ([`CODEX_SKIP_EVENT_MSG_TYPES`](https://github.com/Wynelson94/longhand/blob/main/longhand/codex.py): the UI mirrors of canonical messages, and turn bookkeeping) — mostly pure harness bookkeeping (queue markers, progress pings, usage and state snapshots) — are recognized and skipped rather than stored. That's not quite "zero content dropped," though: one of those types, `attachment`, can carry a queued follow-up prompt in its own `attachment.prompt` field, and Codex's encrypted-reasoning and context-compaction (`compacted`) records are dropped outright. Everything else with real content — every ordinary message, tool call, file edit, and thinking block — is kept verbatim.
The "memory crisis" in AI was an artificial constraint. Storage is solved. SQLite is from 2000. ChromaDB is a mature open-source vector store. Both run on a laptop. Longhand bypasses the crisis by ignoring it — your past sessions are already on disk, written by Claude Code itself, in JSONL files that contain every single event verbatim. Longhand reads those files, indexes them locally, and gives you semantic recall over your entire history without ever sending a token through someone else's API.
**Local. Complete. Yours.**
> **Storage footprint:** ~7.5GB for a heavy power user (792+ sessions, 269k+ events, months of daily Claude Code usage across 45 inferred projects — measured 2026-09-27, see [Stats](#stats)). Typical users: 200–400MB. Once Claude Code rotates the source files off disk, Longhand isn't a duplicate — it's the only copy.
---
## Platform support
**Python 3.10 – 3.14 are all fully supported and gated in CI** — branch protection requires the full suite to pass on all five before a PR merges (admins can bypass it — see [CONTRIBUTING.md](https://github.com/Wynelson94/longhand/blob/main/CONTRIBUTING.md)).
Longhand pins `chromadb<1.0` for **every** Python version, not just 3.14. The pin originated with chromadb's newer Rust bindings segfaulting on 3.14 ([#4](https://github.com/Wynelson94/longhand/issues/4), now closed), and it stays until a 1.x chromadb is verified across the whole matrix.
**Windows is not supported. Use WSL2.** A `windows-latest × py3.12` leg runs on every PR, but it's a non-blocking `continue-on-error` step — and it fails. 12 core tests fail on every run (hook install/uninstall idempotency, config-file paths, redaction, live-ingest line counting, demo cleanup, and more — tracked in [#112](https://github.com/Wynelson94/longhand/issues/112)), not flaky edge cases. The job shows green in GitHub's UI only because `continue-on-error` swallows the failed step; it is evidence-gathering, not a claim that Longhand works there. **Linux (3.10–3.14) is the only platform CI actually gates**; there is no macOS leg. macOS is the author's daily-driver OS and where it's validated by hand (see Stats), but it isn't independently verified in CI.
Two things are macOS-specific regardless of the CI matrix: `schedule install-reconciler` installs a launchd job and is a no-op elsewhere (use cron/systemd-user on Linux; on Windows, use WSL2). `mcp install` also only ever writes Claude Desktop's macOS config path ([#105](https://github.com/Wynelson94/longhand/issues/105)) — there's no Claude Desktop release for Linux, and Windows isn't supported ([#112](https://github.com/Wynelson94/longhand/issues/112)); wiring a Windows Claude Desktop to a WSL2 install would mean hand-editing its config to launch Longhand through `wsl.exe`, which is untested.
**Codex Desktop and Codex CLI** threads are captured into the same archive from 1.1.0 — see [Works with Codex](#works-with-codex).
---
## Compatibility
Longhand 1.0 makes five promises, each backed by an enforcement artifact in the repo. The full text is in **[COMPATIBILITY.md](https://github.com/Wynelson94/longhand/blob/main/COMPATIBILITY.md)**; the short version:
1. **Stable surface** — CLI and MCP frozen through 1.x. Removals only at a major version, and only after warning for one full minor.
2. **Forward data compat** — a database written by 0.11+ opens on any later 1.x. Migrations are automatic, one-time, never renumbered. Older code refuses a newer database loudly rather than operating blind.
3. **Hook guarantees** — hooks never raise, never touch the network, never block your prompt.
4. **Upstream drift is never silent** — unknown transcript entries are preserved, surfaced in `doctor`, and regression-gated.
5. **Honest metrics** — counts reflect real signals, and `doctor` never recommends a remedy that cannot work.
**Deprecation policy:** anything slated for removal warns for at least one full minor release first, and the warning names its replacement. Retired MCP tool names are the one thing that never goes away — they leave the tool listing but keep answering forever with a migration note, because those names live in users' own `CLAUDE.md` files.
---
## Longhand vs claude-mem
[`thedotmack/claude-mem`](https://github.com/thedotmack/claude-mem) is the most popular Claude Code memory tool on GitHub (55k+ stars). It's a good tool. It is also solving the memory problem in the opposite direction from Longhand, and the difference is worth understanding before you pick one.
| | claude-mem | Longhand |
|----------------------------|----------------------------------------------|----------------------------------------------|
| **What's stored** | AI-generated summaries / "observations" | Verbatim events from the raw JSONL |
| **Who decides what's kept**| An LLM, at write time | Nobody — no summarizer filters it |
| **Compression** | Semantic (lossy, by design) | None (lossless) |
| **API calls per session** | One or more (calls Claude to summarize) | Zero |
| **Thinking blocks** | Typically folded into summaries | First-class, stored verbatim |
| **Deterministic replay** | No — summaries can't reconstruct file state | Yes — every diff kept and replayable |
| **Model portability** | Tied to the summarizer's output | Same data works across any model, forever |
| **Runtime** | TypeScript, Bun, HTTP worker on :37777 | Python, no server |
| **License** | AGPL-3.0 | MIT |
The philosophical split: **claude-mem asks an AI what was important and keeps that. Longhand keeps the actual bytes and lets you decide later.** If you trust a model's judgment about its own past, claude-mem's approach is cheaper at query time (pre-summarized) and easier on storage. If you've ever been burned by a summary that dropped the thing that turned out to matter, Longhand is the tool that never throws anything away.
Both can coexist on the same machine — they operate on the same JSONL files without interfering.
---
## The Principles
Longhand is built on a handful of principles. If you disagree with them, you probably want a different tool.
### 1. Information doesn't disappear — it moves.
When data goes "missing" it's almost never actually gone. It got compressed, summarized, filed somewhere else, or renamed. Find the raw source and the truth is still there waiting. Claude Code already writes every session to disk as JSONL. That file is the raw source. Longhand just reads it.
### 2. Summarization is a lossy decision disguised as a convenience.
Most AI memory systems read a conversation and ask the AI to write down "what mattered." The AI is now the gatekeeper of its own memory, and the AI has incentives — brevity, confidence, coherence — that aren't the same as truth. You end up with a story about what happened instead of what happened.
Longhand never summarizes. It stores the complete record and lets you query it.
### 3. The raw record is cheap. Acting like it isn't wastes it.
A full Claude Code JSONL file is kilobytes to low megabytes. A year of daily sessions is hundreds of megabytes. That is nothing on modern hardware. There is no engineering reason to throw the data away. Summary-based memory isn't saving space — it's giving away information that was free.
### 4. The thinking is the most valuable part.
When Claude produces a `thinking` block, that's the reasoning behind the decision — usually invisible to the user, almost always more useful than the final answer. Summary-based memory throws thinking blocks away because they're "internal." Longhand treats them as first-class events. "What was I thinking when I chose to use a conditional update?" pulls the verbatim thinking block that contains the answer.
### 5. A fix you can't reproduce is a fix you didn't keep.
If you fixed a bug in March, the state of that file when the bug was fixed is a fact. Longhand reconstructs it deterministically by applying every edit in sequence from the session JSONL. No guessing, no AI inference, just literal application of the diffs. You can see the exact state of any file at any point in any past session.
### 6. Memory should be proactive, not just searchable.
A searchable archive is useful but passive. Real memory answers fuzzy questions. "A couple months ago I was building a game that kept breaking, then you fixed it — bring that fix forward." Longhand parses the time phrase, matches the project, finds the problem→fix episode, and returns the diff. You don't have to know the session ID. You just have to remember that it happened.
### 7. Deterministic beats clever.
Everything in Longhand's analysis is rules-based. Regex error detection. Hash-based project IDs. Forward-walking episode extraction. No LLMs in the core pipeline. That means fast (~128ms median warm recall — measured 2026-09-27, see [Stats](#stats)), reproducible (same input → same output), and fully local (no API keys, no cloud). An LLM layer could go on top later, but the foundation runs on laws, not on a model's opinion.
### 8. Local or nothing.
Your Claude Code history is yours. It goes into a SQLite file and a ChromaDB directory in `~/.longhand/`. No telemetry. No sync. No account. If your laptop is offline, Longhand works. If Anthropic goes down, Longhand works. If you delete the directory, it's gone.
One boring exception, disclosed in full: the interactive CLI checks pypi.org for a newer Longhand version. Most commands respect a 24-hour cache and print any hint only after their own output, so nothing you're waiting on is delayed. `doctor` (and `setup`, which runs it) is the exception — it forces a fresh, synchronous fetch every time, with a 2-second timeout, before it prints its table. The request carries nothing but itself — no telemetry, no identifiers, nothing about your corpus. It's excluded from Claude Code's hooks and from the `mcp-server` entry point `mcp install` actually configures for Claude Desktop, but not yet from `longhand shared-mcp`, `mcp serve`, or `demo` — those currently run the same check at exit like any other command ([#101](https://github.com/Wynelson94/longhand/issues/101)). `LONGHAND_NO_UPDATE_CHECK=1` turns all of it off. "Zero API calls" means what it always meant: no LLM or cloud service ever touches your data.
---
## What It Actually Does
When you use Claude Code, every session writes a JSONL file to `~/.claude/projects/<project>/<session-id>.jsonl`. That file contains every message, every tool call, every thinking block, every file edit with full before/after content, and a millisecond-precise timestamp for each event.
Longhand reads those files. Then it gives you:
- **Semantic search** across every event you've ever generated
- **Filterable search** — by tool, file, session, project, and event type — all filters combinable (MCP `search`; the CLI `search` command has tool/file/session/type but no project filter, and neither has a time-range filter)
- **Tool call archaeology** — "show me Bash commands that touched Supabase" — ranked by relevance, not literally every match; scope to a session or project to cut noise
- **File history across sessions** — every edit to a specific file, chronologically, across all your sessions
- **Session replay** — reconstruct any file's state at any point in any past session
- **Reasoning retrieval** — query Claude's verbatim thinking blocks
- **Timeline view** — chronological playback with pagination (offset, tail, summary-only scan mode)
- **Fuzzy recall** — natural-language questions about past work ("that race condition fix from last week")
- **Project inference** — automatic detection of which projects you've worked on, with categories and aliases
- **Episode extraction** — automatic detection of problem→fix sequences in your sessions
- **Conversation segments** — topic-level clustering (stories, design discussions, debugging, planning) so recall finds the *why*, not just the *what*
- **Git-aware project recall** — ask "where did we leave off on X" and get recent commits, unresolved issues, last session outcome in one call
- **Git commit extraction** — structured extraction of every git commit, push, merge, checkout from sessions, linked to episodes
- **MCP server** — 13 tools that let Claude query Longhand directly during live conversations
- **Auto-ingest hook** — drops into Claude Code's `SessionEnd` hook so new sessions are indexed automatically
- **Live ingestion** — the `Stop` hook (installed alongside `SessionEnd` by `hook install`; not separately optional) tails the active transcript between turns so an in-flight session is queryable immediately via `list_sessions`, timeline, file history, and replay. It stores events only, no embeddings — semantic `recall`/`search` still wait for the `SessionEnd` pass, or for a `reconcile --fix` pass to pick it up (the live tail never sets `project_id`, so reconcile treats it as needing a full re-ingest)
- **Plan history** — every Write/Edit to `~/.claude/plans/*.md` is captured as a first-class entity, queryable via `longhand plans list` and the `list_plans` MCP tool
- **Secret redaction (opt-in)** — `longhand config --set redact.enabled=true` masks secret-shaped strings (API keys, tokens, JWTs, DB passwords) at ingest before they reach the index; `longhand redact --apply` retroactively masks data ingested earlier (see [SECURITY.md](https://github.com/Wynelson94/longhand/blob/main/SECURITY.md) for the current gap in git commit message coverage, [#110](https://github.com/Wynelson94/longhand/issues/110))
- **Background reconciler** — optional launchd job (`longhand schedule install-reconciler`) keeps the index honest without manual `reconcile --fix` runs
- **Context injection** — `UserPromptSubmit` hook auto-injects relevant past context before Claude sees your message (configurable threshold and size cap); prints the same age-gap `Note: …` line as `recall` when the injected context is old and stale-looking relative to fresher work
- **Configurable** — `longhand config` to tune injection relevance, token budget, and behavior without editing code
---
## Install
```bash
pip install longhand
longhand setup
```
That's it. `longhand setup` backfills your existing Claude Code history, installs the hooks that keep it updated automatically, registers Longhand as an MCP server for Claude Desktop, prints the one-line command to add it to Claude Code (`claude mcp add longhand -s user -- longhand mcp-server`), and verifies everything works. About two minutes the first time, zero maintenance after that.
To upgrade later: `pip install -U longhand`.
### Developer install (from source)
```bash
git clone https://github.com/Wynelson94/longhand.git
cd longhand
pip install -e .
longhand setup
```
<details>
<summary>Or run the individual commands yourself</summary>
```bash
longhand ingest # ingest all your existing Claude Code history
longhand analyze --all # run analysis (projects, outcomes, episodes, segments)
longhand hook install # wires both SessionEnd and Stop hooks (installed together)
longhand prompt-hook install # (optional) auto-inject past context into new prompts
longhand mcp install # register Longhand as an MCP server for Claude Desktop
claude mcp add longhand -s user -- longhand mcp-server # ...and for Claude Code
longhand schedule install-reconciler # (optional, macOS-only) launchd job to run reconcile --fix periodically
longhand config # view/tune hook behavior (relevance threshold, injection size)
longhand doctor # verify everything is wired up
```
`longhand ingest-live` isn't in this list on purpose — it's primarily the hidden entry point the Stop hook calls...
© Wynelson94 · MIT · Wynelson94/longhand


